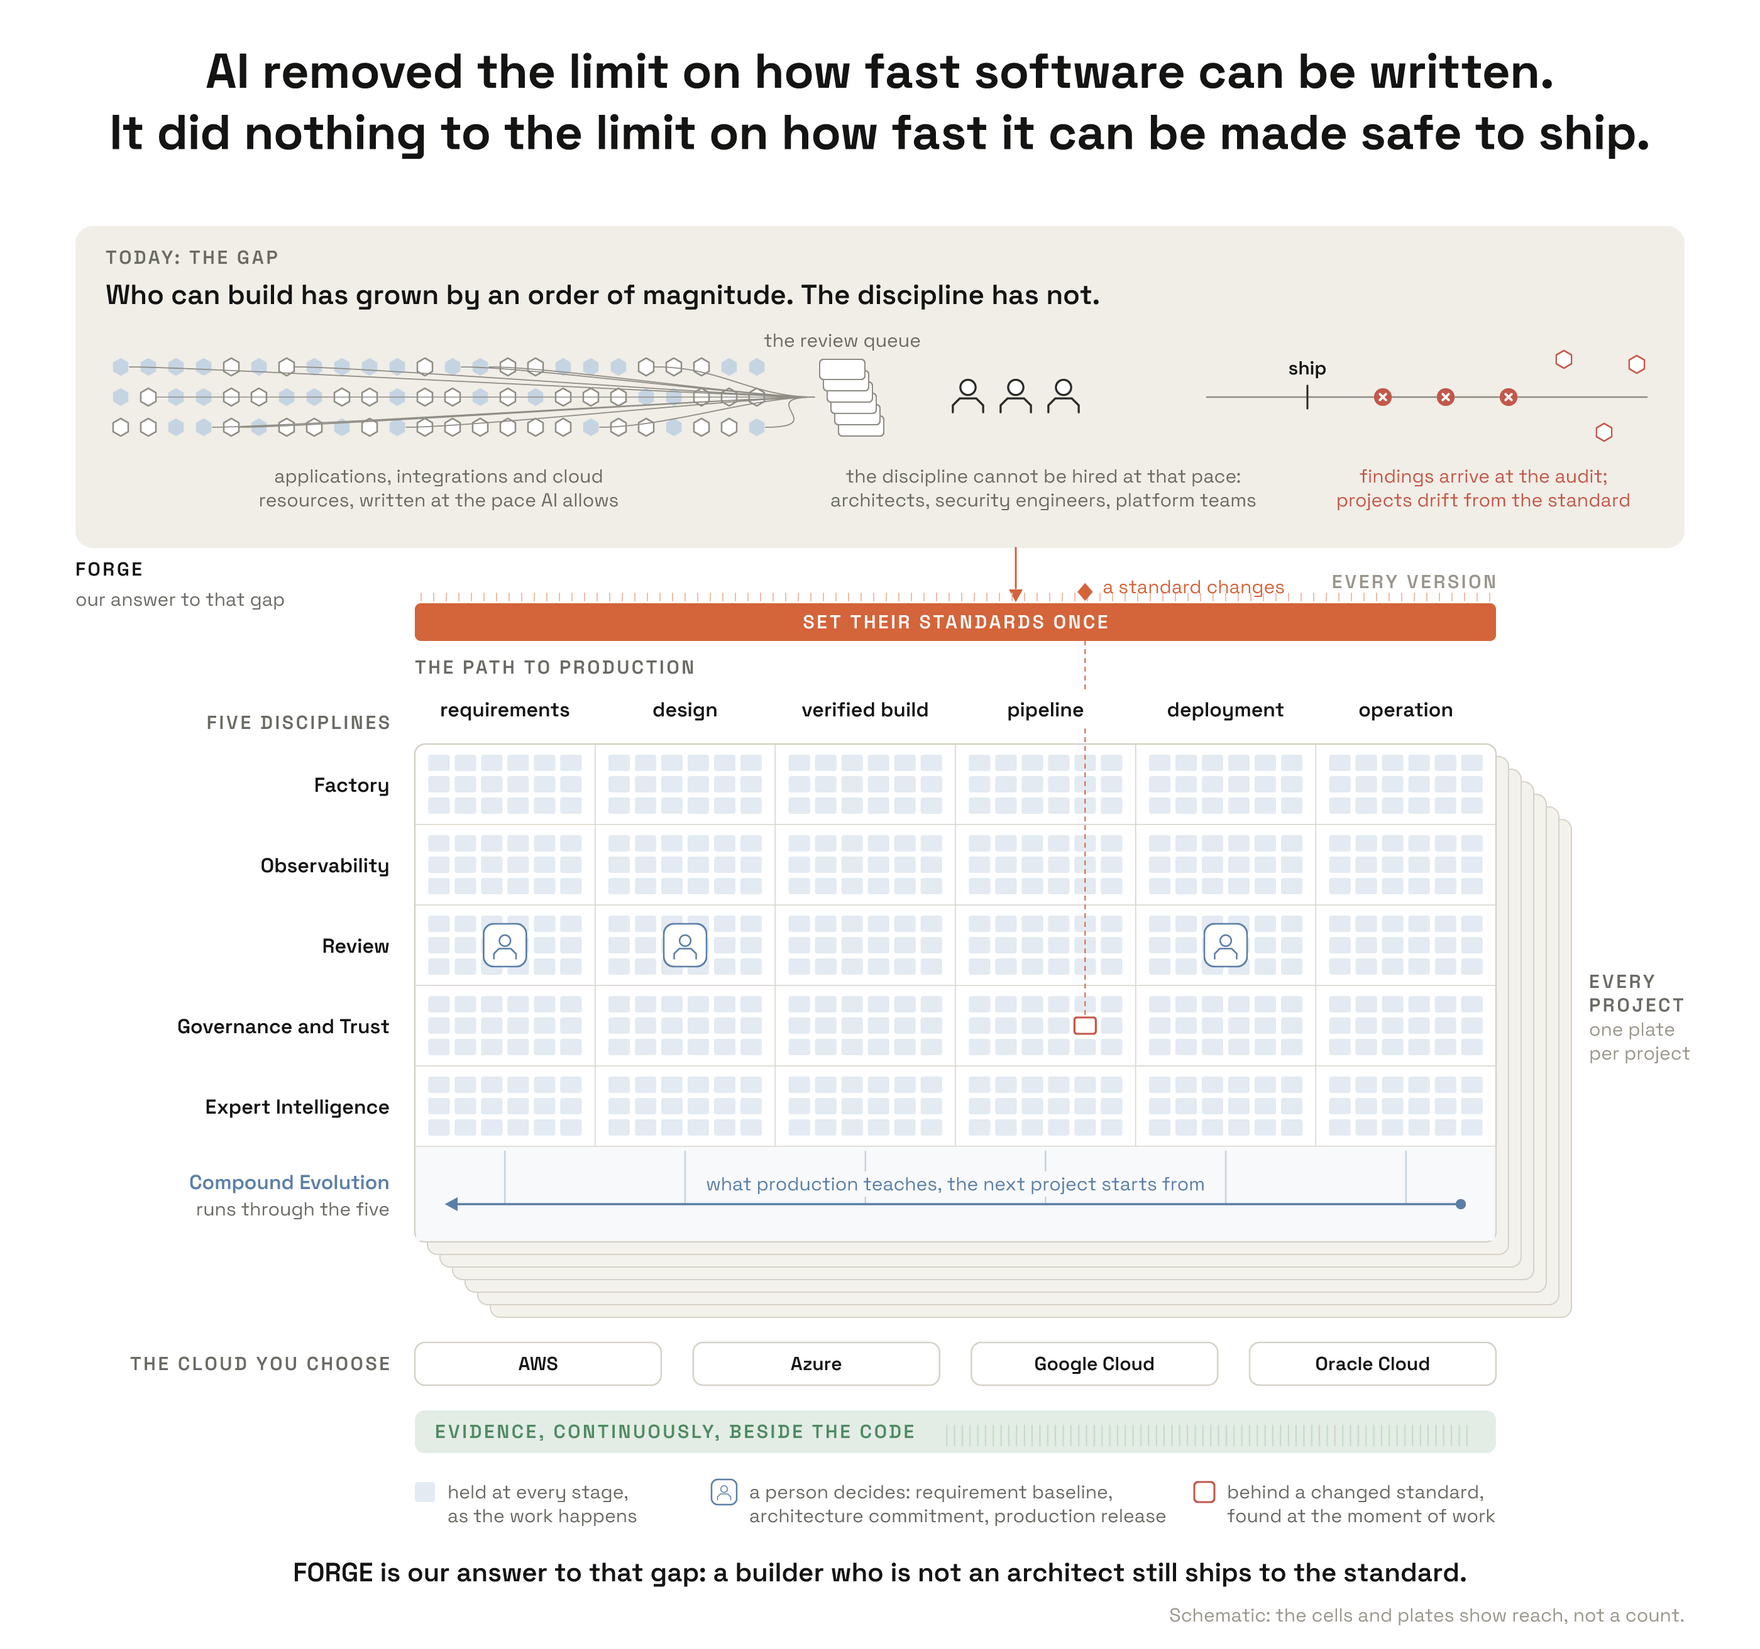
AI removed the limit on how fast software can be written. It did nothing to the limit on how fast software can be made safe to ship. The number of people who can now produce applications, integrations and cloud resources has grown by an order of magnitude. The discipline that makes that output fit for an enterprise has not, and it cannot be hired at that pace. FORGE is our answer to that gap. It is our product, an engineering platform, and the method it runs. Your architects, security engineers and platform teams set their standards once. FORGE builds those standards into the path to production for every project, so a builder who is not an architect still ships to the standard.
Five disciplines do the work: Factory, Observability, Review, Governance and Trust, and Expert Intelligence. A sixth, Compound Evolution, runs through the other five. Each is an engineering property of the path, running as the work happens. Each build leaves with the evidence that it ran under them, as an output beside the code. The path starts with requirements, written new or recovered from a system you already run. It runs through a verified build, a generated pipeline and an infrastructure-as-code deployment on the cloud you choose. It ends in operation, with an operator built from the system's own design. The evidence is continuous across all of it.
The name is from the craft. Forging is how the parts that must not fail are made. Metal shaped under controlled heat and pressure comes out with its grain following the shape of the part. That is why a forged part is stronger than the same metal cast or cut. Your standards and controls are the die. Every build passes through the same one, so the discipline runs through the grain of what ships instead of being applied to the surface afterwards. The letters name the five disciplines, and this brief takes them in the order they operate.
BtSavvy's forward-deployed engineers build on FORGE with your team, inside your repositories and your cloud accounts. They teach the product and the discipline as they go. Adopt FORGE on its own, or have our engineers build and operate production AI systems on it with you.
Factory
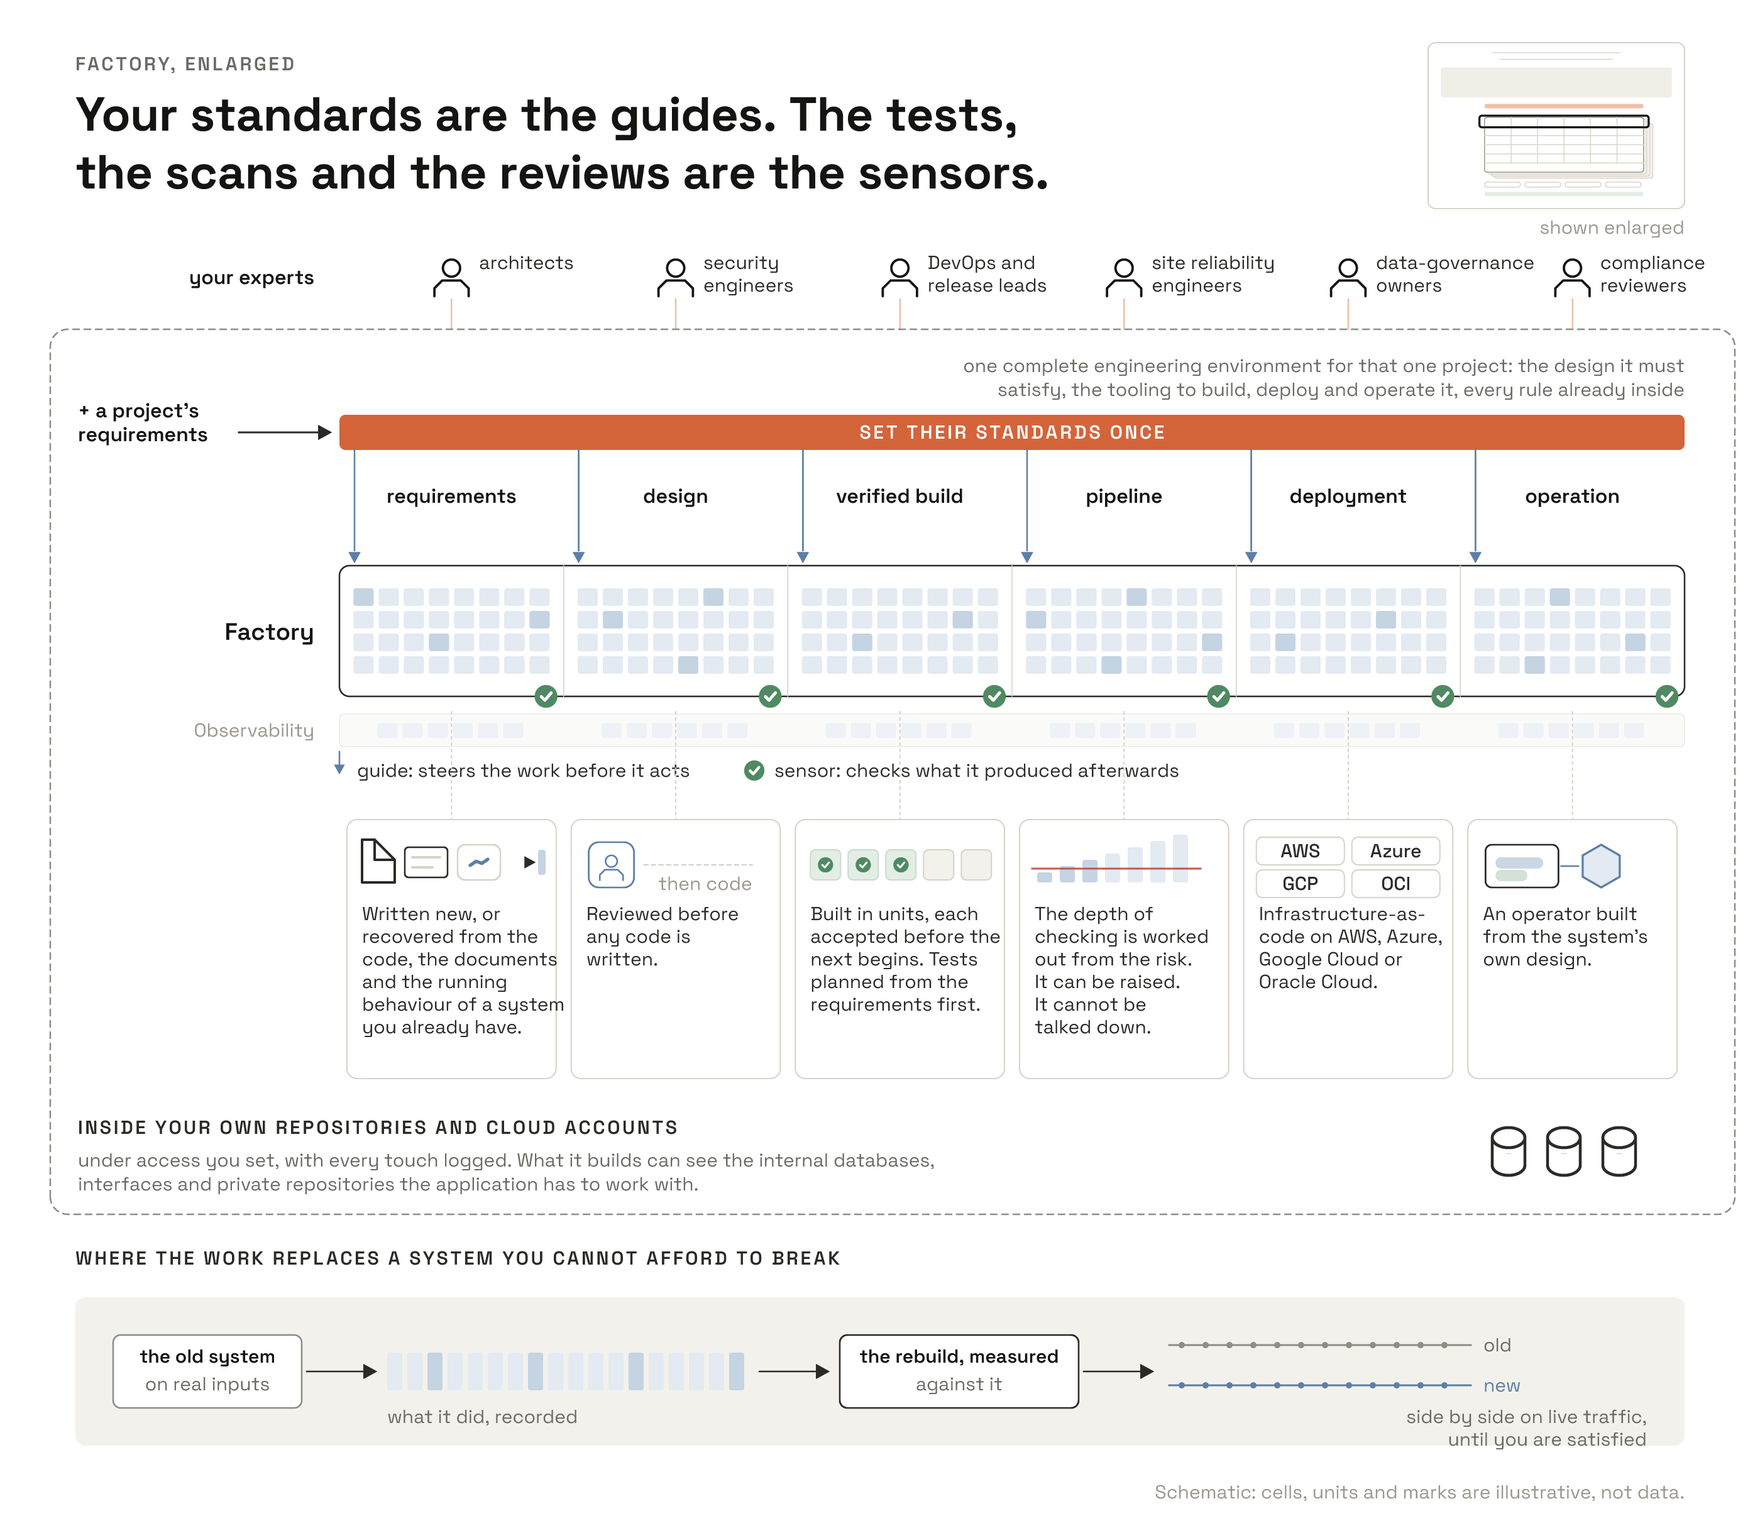
Factory is where your experts set the discipline a build must follow, once. Your architects, security engineers, DevOps and release leads, site reliability engineers, data-governance owners and compliance reviewers document their standards in FORGE. From a project's requirements and those standards, FORGE produces a complete engineering environment for that one project. It holds the design the software must satisfy and the tooling to build, deploy and operate it, with every rule already inside. The requirements are written new, or recovered from the code, the documents and the running behaviour of a system you already have. The design is reviewed before any code is written. Work is built in units, each accepted before the next begins, and the tests are planned from the requirements before the code exists. The depth of checking is worked out from the risk a change carries. It can be raised, and it cannot be talked down. Where the work replaces a system you cannot afford to break, FORGE records what the old system did on real inputs. The rebuild is measured against that recorded behaviour before cut-over, and the comparison runs on live traffic until you are satisfied.
The environment runs inside your own repositories and cloud accounts, under access you set, with every touch logged. What it builds can see the internal databases, interfaces and private repositories the application has to work with. What ships fits the enterprise it runs in. Your developers work in it with the AI tools they already use. Deployment is infrastructure-as-code on AWS, Azure, Google Cloud (GCP) or Oracle Cloud (OCI), whichever the workload needs. The modules come from the provider where they fit and from our labs where they do not. Inside the environment, predictable work runs as plain code and a model is used where judgement is needed. Anthropic's Building Effective Agents argues for the same posture: simple, composable patterns, and a fixed code path wherever a task is well defined (Anthropic, 2024). Birgitta Böckeler, writing on martinfowler.com, names the two kinds of control that make this reliable. Guides steer a coding agent before it acts; sensors check what it produced afterwards (Böckeler, martinfowler.com, 2026). Your standards are the guides. The tests, the scans and the reviews are the sensors.
Project-by-project delivery starts again on every project. A factory compounds. Kieran Klaassen at Every named this shift compound engineering: each piece of engineering work should make the next one easier (Klaassen, Every, 2025). Andrej Karpathy's Software 2.0 is the earlier statement of the same direction. A growing share of software is produced by stating what is wanted and letting a system find the program (Karpathy, Software 2.0, 2017). OpenAI reported in 2026 that a small team shipped an internal product of roughly a million lines in five months with no hand-written source code. It did so by putting its engineering effort into the environment the agents worked in (OpenAI, 2026). FORGE is built on the compounding principle. A standard hardened or a mistake designed out on one build is inherited by the next. The standards, the patterns and the reference builds live in your repository as plain, versioned files. They are yours after the engagement and portable out of it.
Observability
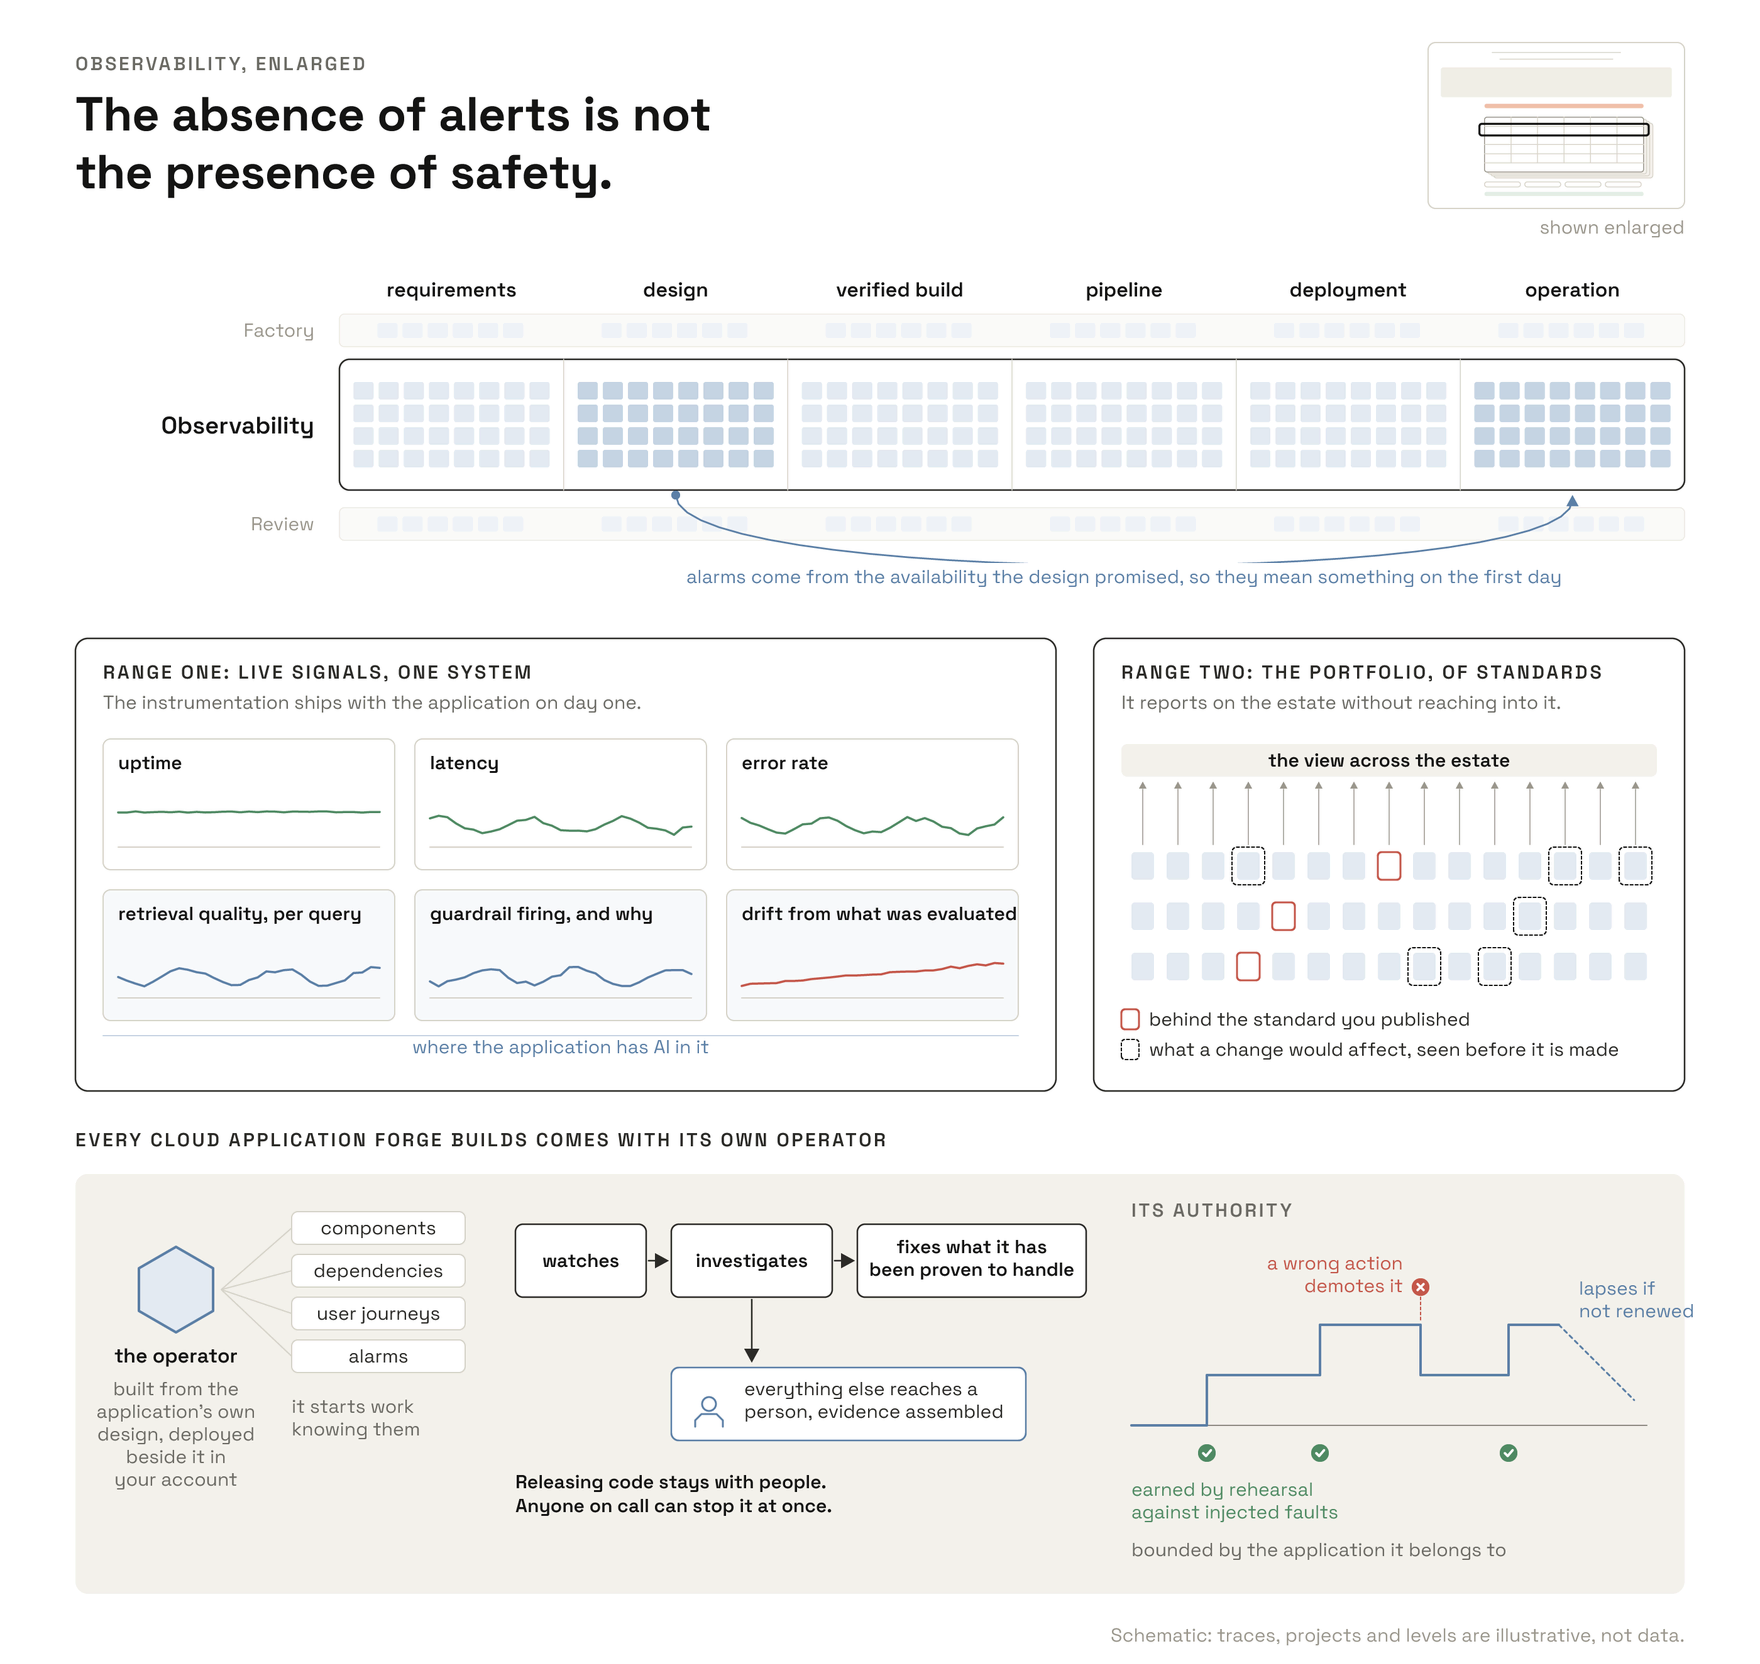
Observability is how you see what is being built and how it behaves once it is live. It works at two ranges that should not be confused. Live operational signals belong to one system. The portfolio view is of standards: which projects are behind the one you published, and what a change would affect before you make it. It reports on the estate without reaching into it. Under FORGE the per-system signals begin at design time. Alarms come from the availability the design promised, so they mean something on the first day. The system is built to withstand the failure of what it depends on, and to be returned to a known good state. Operations documentation is generated from the system itself, so it describes what was built. Where the application has AI in it, the signals go past uptime and latency. FORGE watches how well retrieval answers each query, and how often a guardrail fires and why. It watches whether the model's behaviour has drifted from what was evaluated. The instrumentation ships with the application on day one.
Every cloud application FORGE builds comes with its own operator, built from the application's own design and deployed beside it in your account. It starts work knowing the components, the dependencies, the user journeys and the alarms, because it comes from the same design. It watches the application, investigates when something goes wrong, and fixes the problems it has been proven to handle. Everything else reaches a person with the evidence already assembled. Its authority is earned by rehearsal against injected faults, bounded by the application it belongs to, and lapses if it is not renewed. A wrong action demotes it. Releasing code stays with people, and anyone on call can stop it at once. Everything it does, and everything it declines to do, is on the record.
The discipline rests on two bodies of work. Google's Site Reliability Engineering is the established base for operating systems at scale (Beyer, Jones, Petoff and Murphy, Site Reliability Engineering, 2016). Its service-level objectives, error budgets and blameless post-mortems are the vocabulary the operator works in. The second is older. How far people rely on an automated system, and whether that reliance matches how reliable it is, has been studied for decades. The foundational paper is Lee and See, Trust in Automation: Designing for Appropriate Reliance (Human Factors, 2004). An agent that looks healthy on an uptime graph can be producing output nobody should act on. FORGE treats that reliance as an operating property of the running system, watched beside latency and error rate. The application is judged on whether it is keeping the promises it made to its users, as well as on whether it is up. The absence of alerts is not the presence of safety.
Review
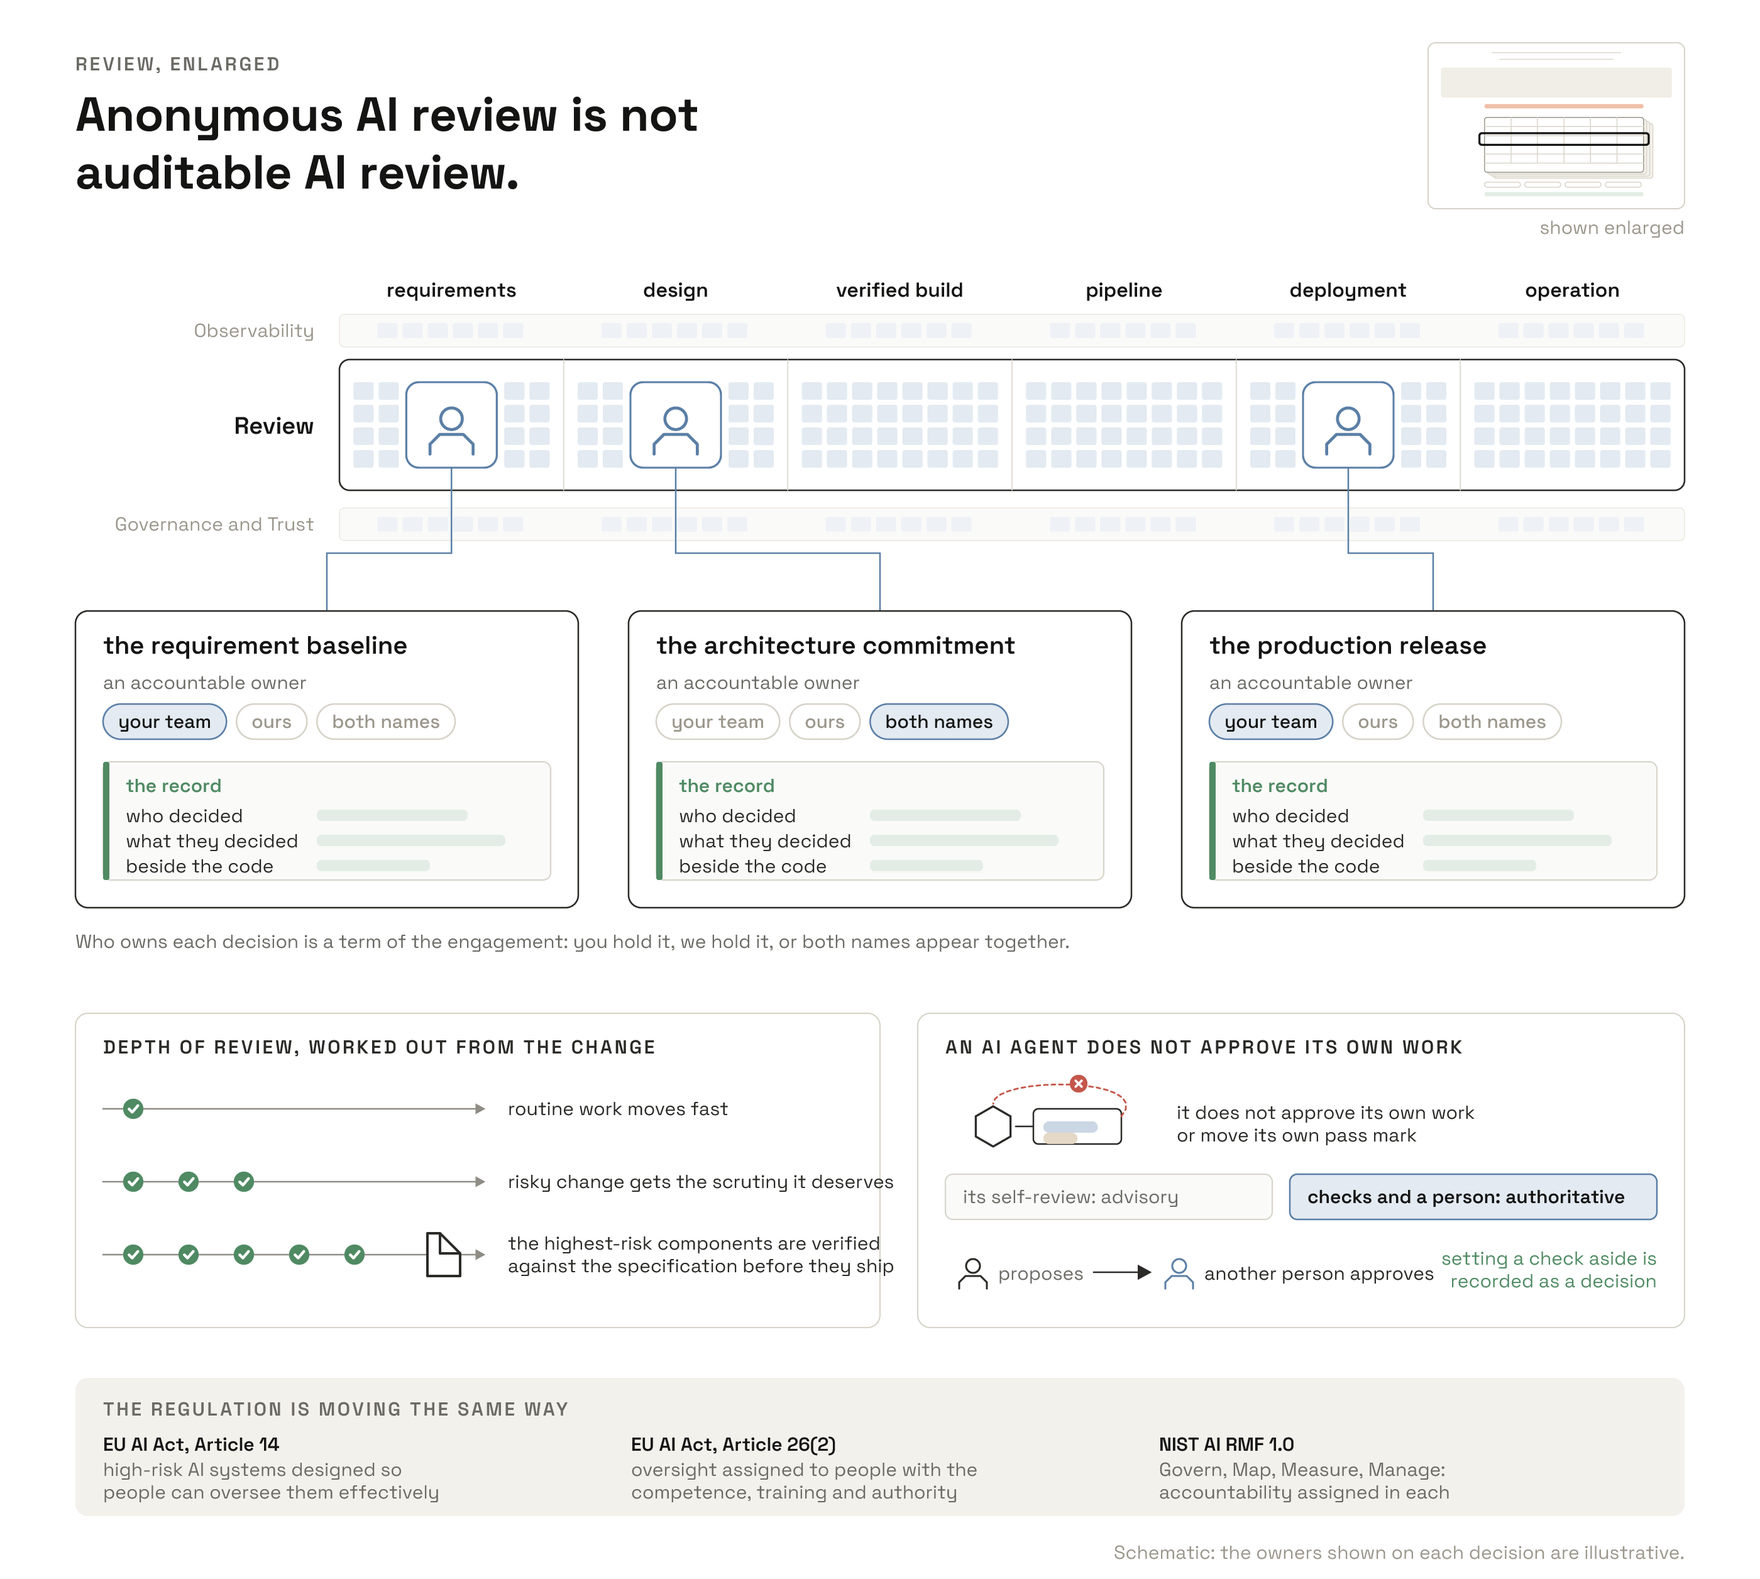
Review is how a decision gets an owner. Everyone with a stake in what ships owns the part that falls to them: architects, security and risk, operations, developers, delivery managers and compliance. The decisions that matter carry an accountable owner from your team, ours, or both. Each is recorded at the point where a wrong autonomous decision would be expensive: the requirement baseline, the architecture commitment, the production release. The record is produced as the work happens, by the path itself, as a durable artefact that outlives the meeting. The path cannot produce code without producing that record beside it, so an audit is a lookup, not a reconstruction. The depth of review is worked out from the change itself. Routine work moves fast, risky change gets the scrutiny it deserves, and the highest-risk components are verified against the specification before they ship. An AI agent does not approve its own work or move its own pass mark. Its self-review is advisory; mechanical checks and a person's decision are authoritative. Setting a check aside is itself recorded as a decision someone made. A change is approved by someone other than the person who proposed it.
The regulation is moving the same way. The EU AI Act requires high-risk AI systems to be designed so that people can oversee them effectively (Regulation (EU) 2024/1689, Article 14). The organisations that deploy them must assign that oversight to people with the competence, training and authority to exercise it (Article 26(2)). The NIST AI Risk Management Framework sets out four functions, Govern, Map, Measure and Manage, with accountability assigned in each (NIST, AI RMF 1.0, 2023). Anonymous AI review is not auditable AI review. Who owns each decision is a term of the engagement: you hold it, we hold it, or both names appear together. You can hold, share or delegate each class of decision separately.
Governance and Trust
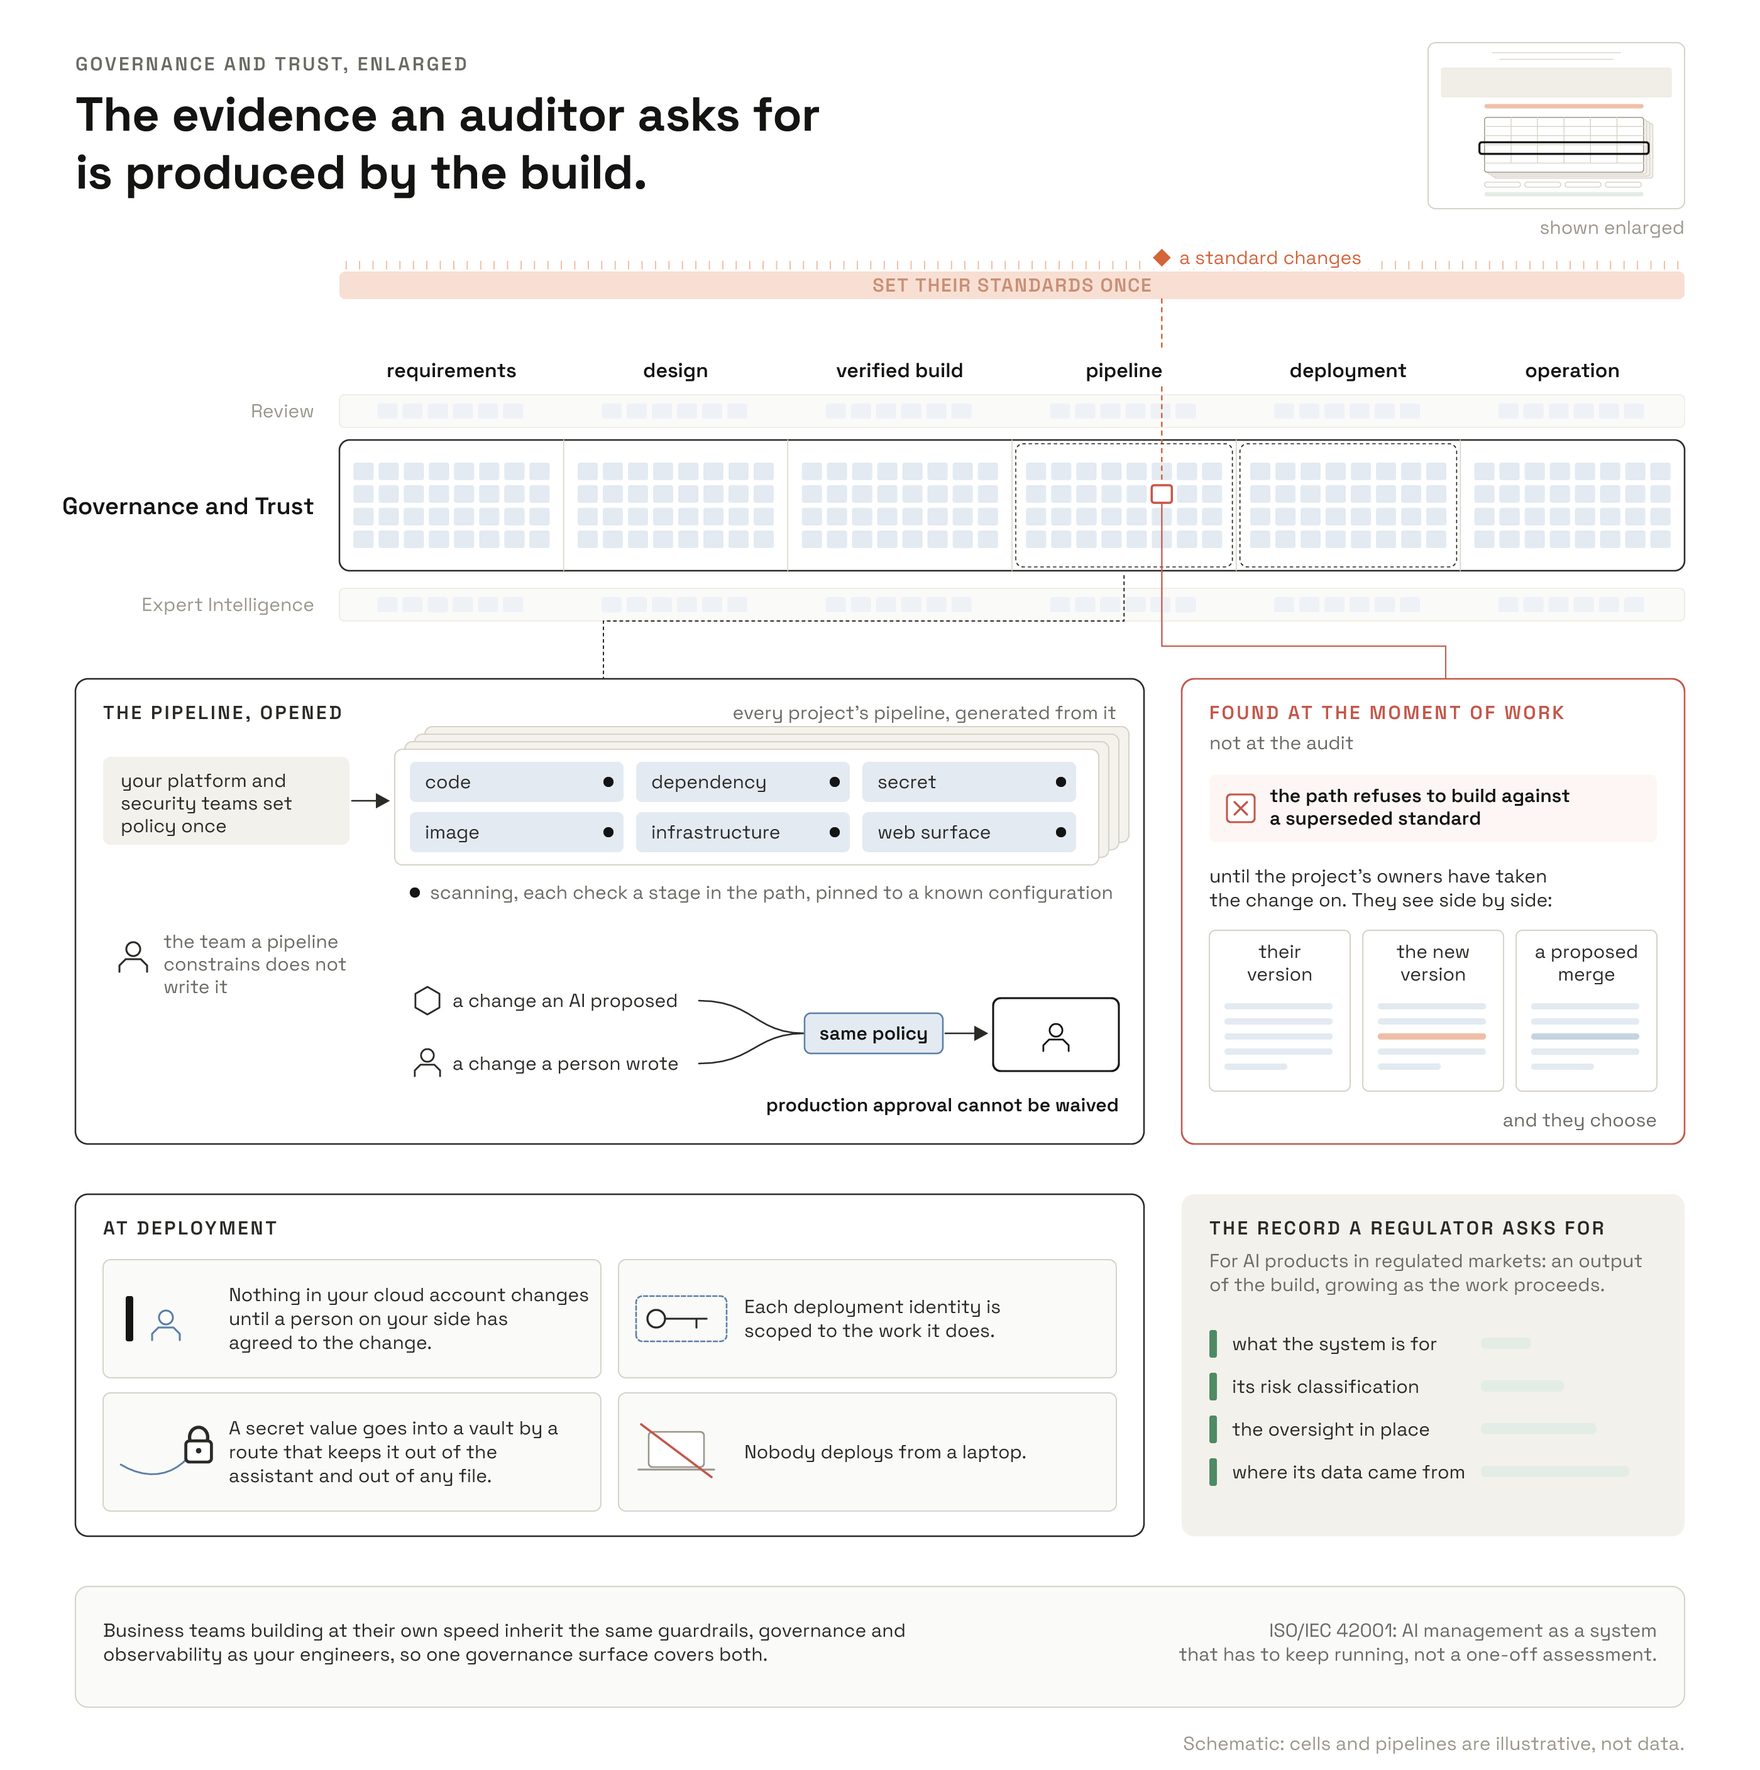
Governance and Trust is how your rules run inside the pipeline, so the evidence an auditor asks for is produced by the build. Your platform and security teams set policy once. Every project's pipeline is generated from it, so the team a pipeline constrains does not write it. Full DevSecOps deployment across AWS, Azure, Google Cloud (GCP) and Oracle Cloud (OCI), with the pipeline tooling you already run, hosted or on premises. The checks are stages in the path: code, dependency, secret, image, infrastructure and web-surface scanning, each pinned to a known configuration. Policy-as-code runs on a machine-proposed change exactly as it runs on a human one. Production approval cannot be waived. Secrets stay outside the AI tool chain. A secret value goes into a vault by a route that keeps it out of the assistant and out of any file. Each deployment identity is scoped to the work it does. Nothing in your cloud account changes at deployment until a person on your side has agreed to the change. Nobody deploys from a laptop.
A standard is set once and inherited by every project. Before you change one, you can see which projects it would affect. After you change it, a project that has fallen behind is found at the moment of work, not at the audit. The path refuses to build against a superseded standard until the project's owners have taken the change on. Business teams building at their own speed inherit the same guardrails, governance and observability as your engineers, so one governance surface covers both. For AI products in regulated markets, the record a regulator asks for is an output of the build. It states what the system is for, its risk classification, the oversight in place and where its data came from. It grows as the work proceeds.
Annual audits do not fit obligations that change between audits, or a model that changes more often than the obligations do. ISO/IEC 42001 sets out AI management as a system that has to keep running, not a one-off assessment (ISO/IEC 42001:2023). The EU AI Act's obligations on high-risk systems run for as long as the system is in use. FORGE is built to that posture. A compliance record produced separately from the delivery record can be contradicted by the delivery it describes. In FORGE the policy enforcement, the data lineage and the name of the person who decided are artefacts of the path that built the system. They are not reports written afterwards for an audit.
Expert Intelligence
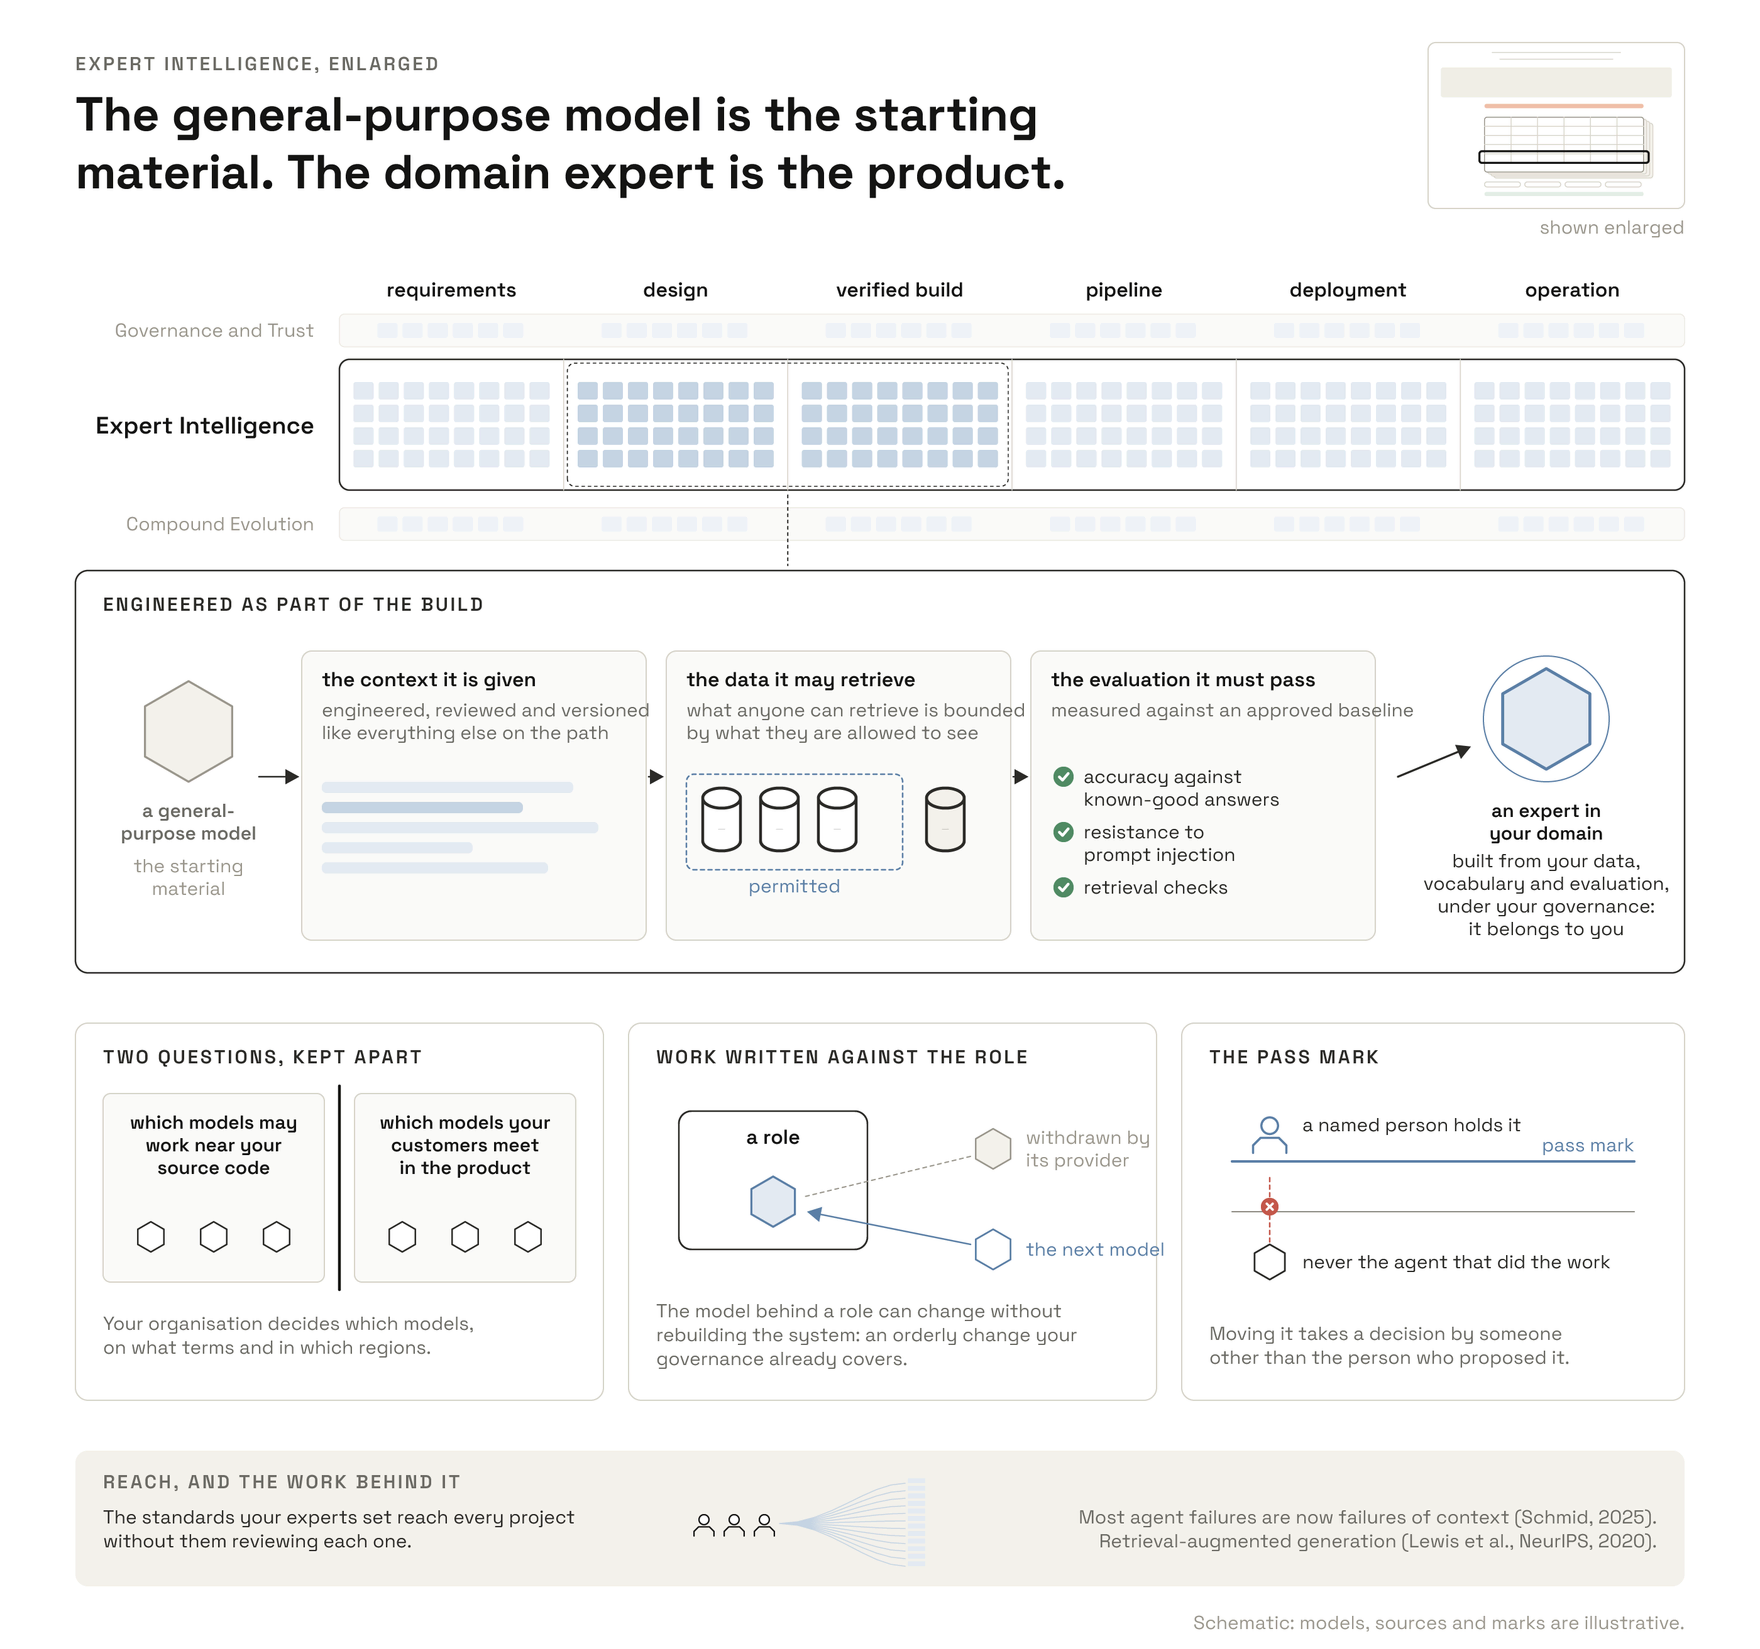
Expert Intelligence is how your scarce experts' judgment reaches further than they could by hand. The standards they set reach every project without them reviewing each one. The same discipline governs the models that do the work, and it takes a general-purpose model to an expert in your domain. Your organisation decides which models may be used, on what terms and in which regions. Two questions are kept apart: which models may work near your source code, and which models your customers meet in the product. Work is written against the role a model plays, so the model behind a role can change without rebuilding the system. A model withdrawn by its provider is an orderly change your governance already covers. The context an application is given, the data it may retrieve and the evaluation it must pass are engineered as part of the build. What anyone can retrieve is bounded by what they are allowed to see. Where the application has AI in it, it carries its own evaluation. Accuracy against known-good answers, resistance to prompt injection and retrieval checks are measured against an approved baseline. The pass mark stays with a named person, never with the agent that did the work. Moving it takes a decision by someone other than the person who proposed the move.
As Philipp Schmid puts it, most agent failures are now failures of context, not of the model. He made that line the centre of context engineering (Schmid, The New Skill in AI is Not Prompting, It's Context Engineering, 2025). FORGE treats the context an agent works from as the main engineering surface of agentic work. What the model is given decides what it can do, and that is engineered, reviewed and versioned like everything else on the path. The mechanism is older than the name. In 2020 Lewis and colleagues gave a general model documents to retrieve and read. It answered knowledge questions more accurately than a comparable model relying only on its training, in more specific and more factual language. The paper that established it is Lewis et al., Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks (NeurIPS, 2020). The general-purpose model is the starting material. The domain expert is the product, built from your data, your vocabulary and your evaluation, under your governance, so it belongs to you.
Compound Evolution
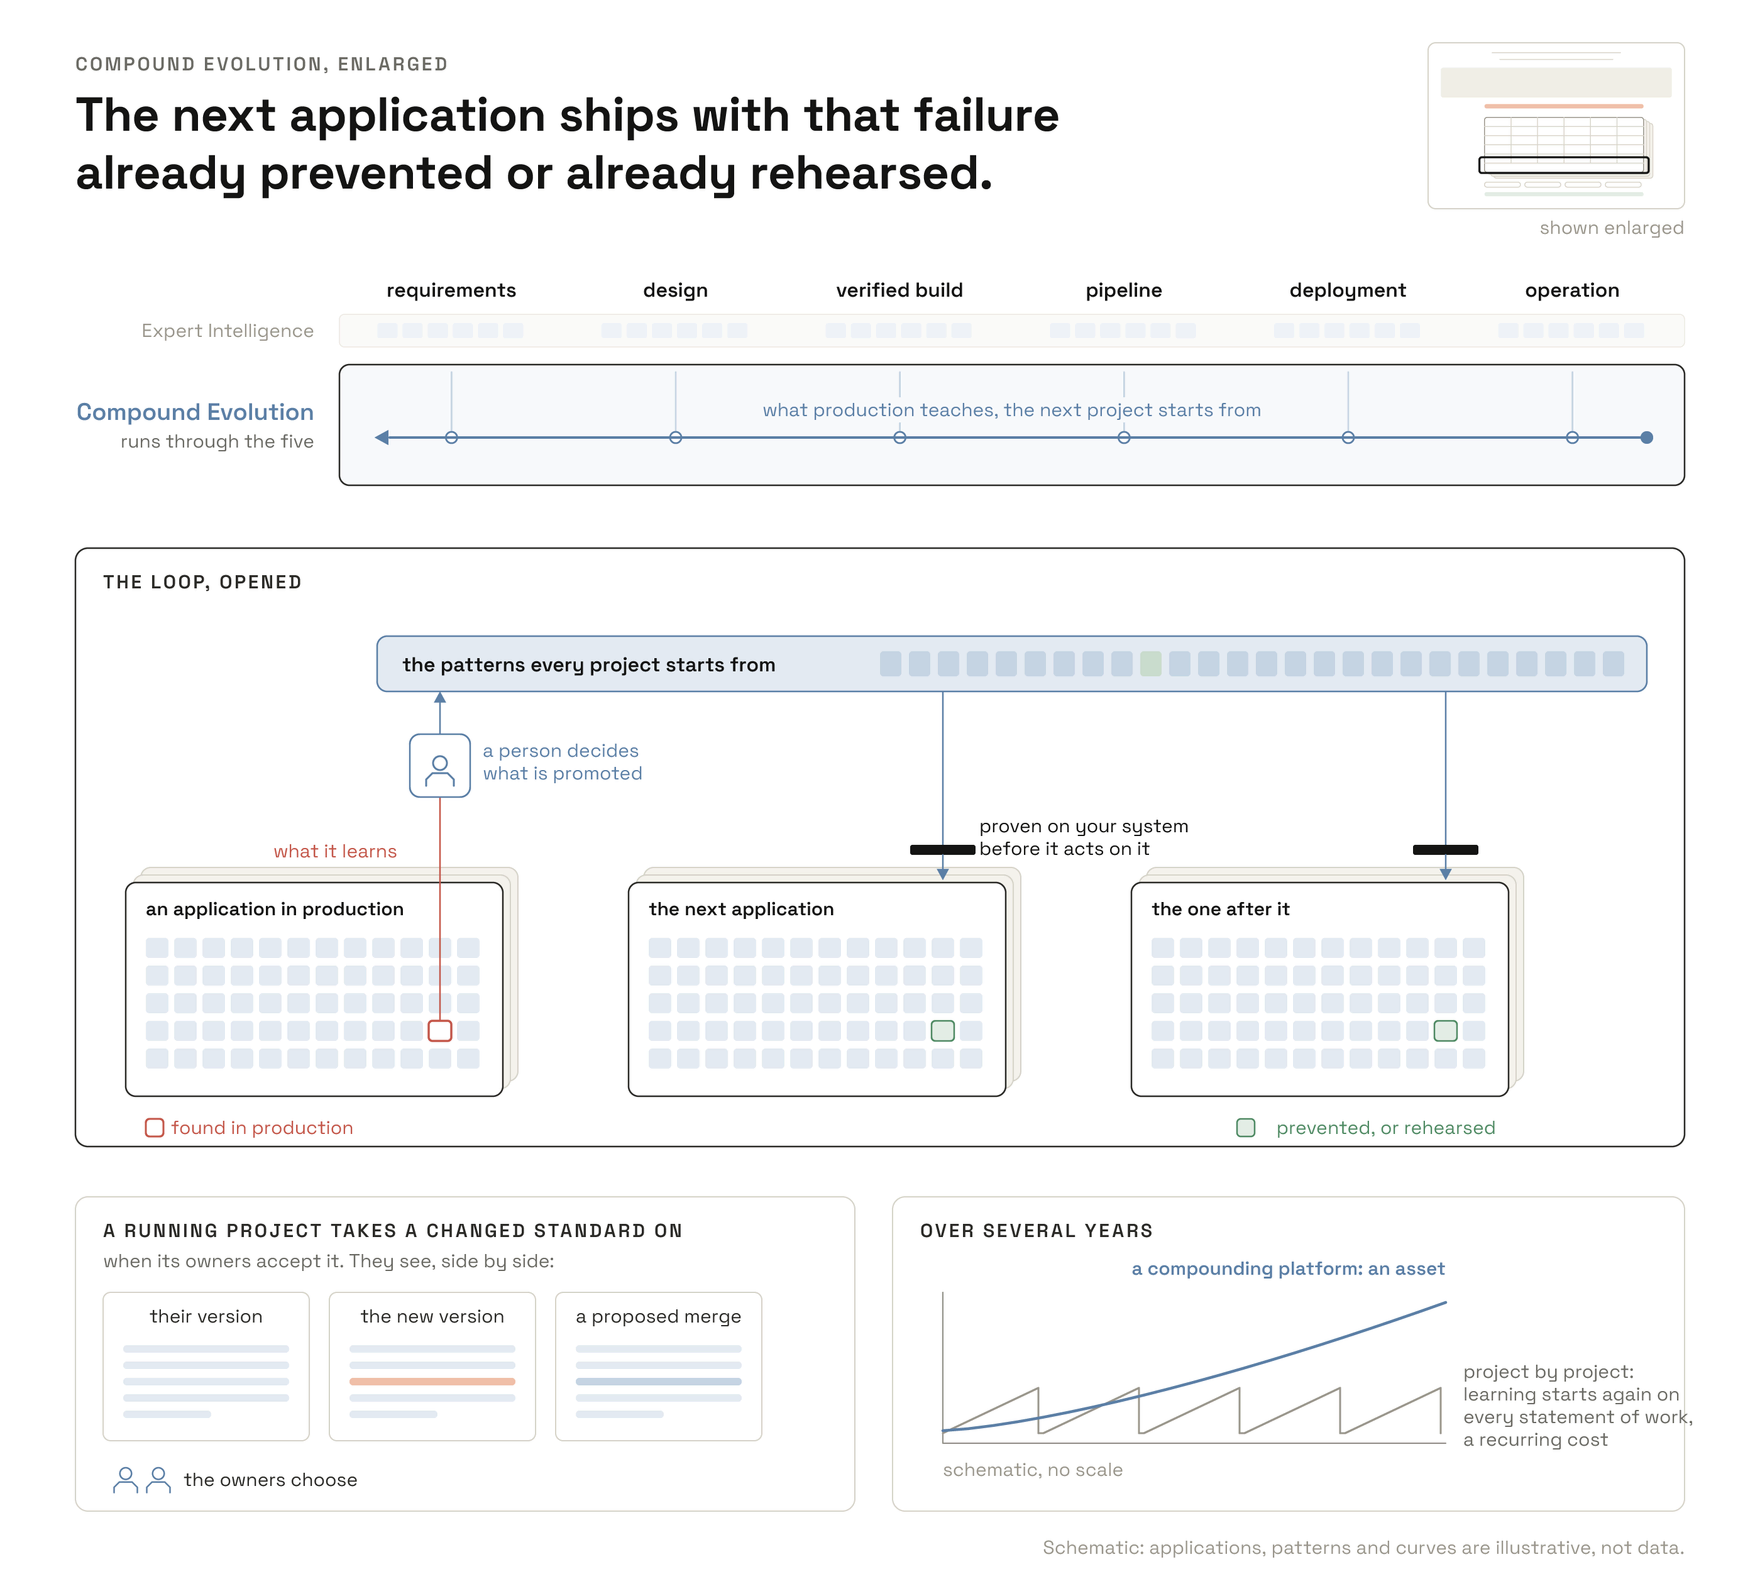
Compound Evolution is the sixth discipline, and it runs through the other five. What one application learns in production goes back into the patterns FORGE builds from. The next application ships with that failure already prevented or already rehearsed. A project that follows another in your estate discovers what the first one built and exposes, and inherits it. The learning is deliberate. A person decides what is promoted into the patterns every project starts from. A running project takes a changed standard on when its owners accept it. They see their version, the new version and a proposed merge side by side. Nothing learned elsewhere acts on your system until it has been proven on your system. Project-by-project delivery starts its learning again on every statement of work. A compounding platform does not, and over several years that is the gap between an asset and a recurring cost.
Compound engineering is the thesis beneath this discipline (Klaassen, Every, 2025). The compounding is an engineering claim about how the platform learns. It is also why the argument against lock-in holds. A capability you would otherwise rent as SaaS can be built with your team on FORGE. It is built to the standard a SaaS provider holds itself to: reliability, operations and evidence. FORGE supplies the design, the tooling and the operator. Your team builds the part that is specific to your business and owns all of it. What gets built lives where your work already lives, so changing a supplier does not mean changing the system.
Where this methodology came from
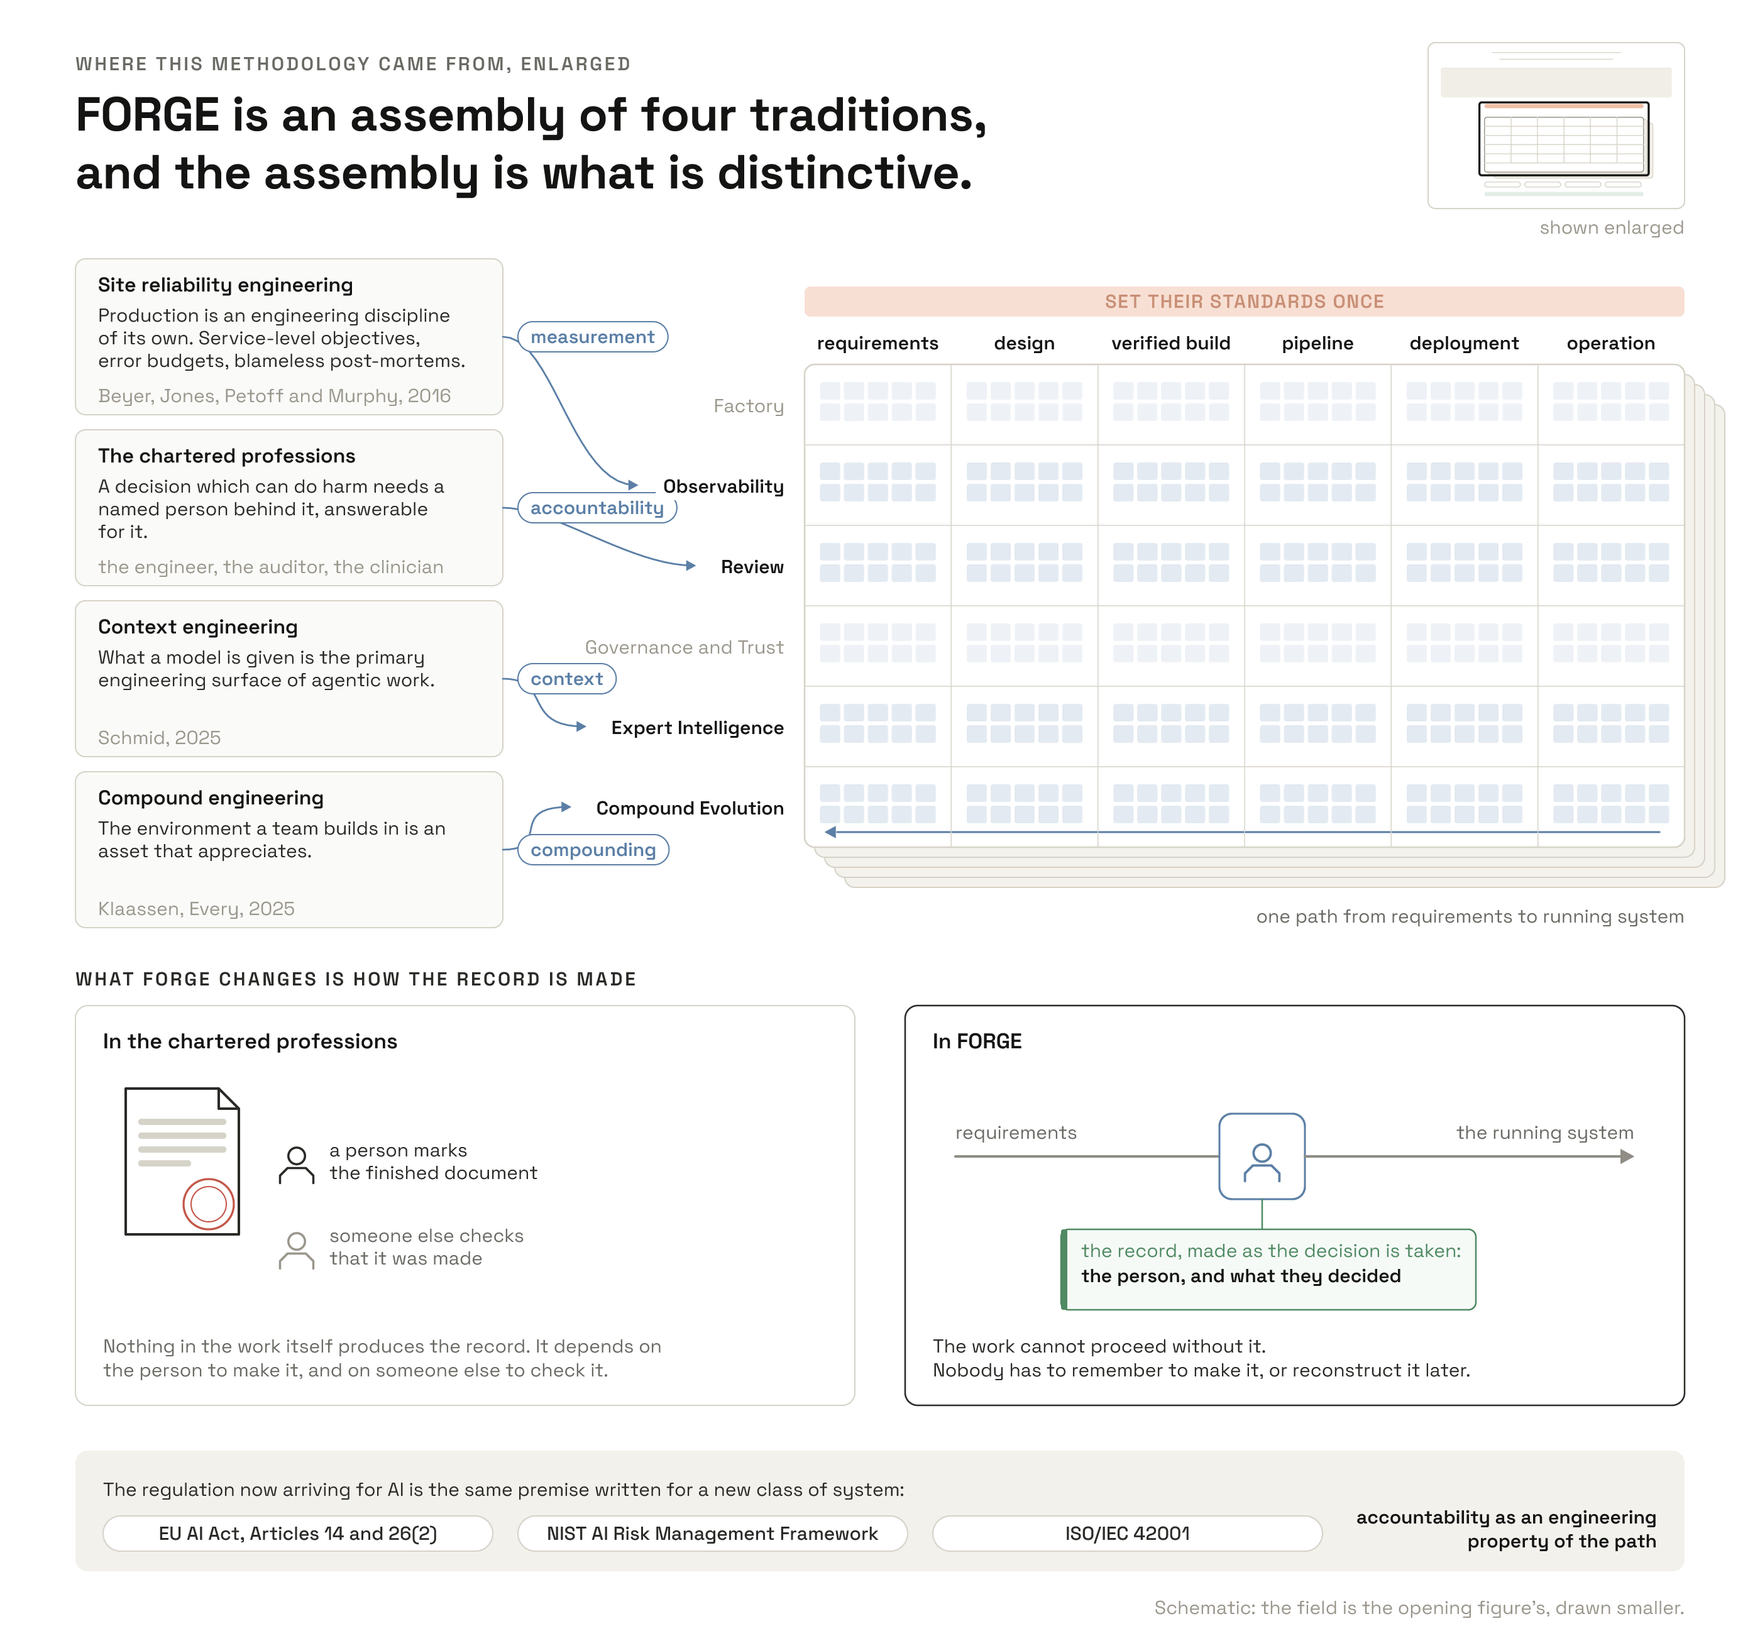
FORGE draws on four engineering traditions. Each contributed a necessary piece, and none alone produces a method that survives production.
From site reliability engineering, FORGE takes the premise that production is an engineering discipline of its own. Google codified the practice and the industry absorbed it (Beyer, Jones, Petoff and Murphy, Site Reliability Engineering, 2016). It has its own measurements, its own failure modes and its own on-call rhythm. Service-level objectives, error budgets and blameless post-mortems are the working vocabulary. FORGE extends that measurement posture onto agent behaviour, because agents fail in ways classical instrumentation does not detect. It gives every cloud application it builds an operator that works in that vocabulary from the first day.
From the chartered professions, FORGE takes the premise that a decision which can do harm needs a named person behind it, answerable for it. The engineer who stamps a drawing has been in responsible charge of the work from its conception, and the stamp records that charge. The auditor who puts their name to an opinion and the clinician who takes responsibility for a discharge stand under the same rule. The record of who decided must outlive the moment of deciding. FORGE inherits the whole of that responsibility: involvement throughout the work, a named person, and the authority to decide. What it changes is how the record is made. In those professions the record is a mark a person makes on the finished document. Nothing in the work itself produces it. It depends on the person to make it, and on someone else to check that it was made. In FORGE the path makes the record at the moment the decision is taken, as a durable artefact beside the code. The work cannot proceed without it. The record names the person and what they decided, so nobody has to remember to make it and nobody has to reconstruct it later. Who holds each decision is a term of the engagement: you, us, or both names together. The regulation now arriving for AI is the same premise written for a new class of system. The EU AI Act places a design duty on the provider (Article 14). It places a duty on the deployer to assign oversight to competent, trained and authorised people (Article 26(2)). The NIST AI Risk Management Framework and ISO/IEC 42001 carry the same premise into risk management. FORGE treats accountability as an engineering property of the path.
From context engineering, FORGE takes the premise that what a model is given is the primary engineering surface of agentic work. The discipline replaces prompt engineering as production systems mature. Retrieval design, evidence assembly and the shape of what the model sees are engineered, reviewed and versioned. The prompts are the smallest part of it. The discipline was named by practitioners in 2025 (Schmid, The New Skill in AI is Not Prompting, It's Context Engineering, 2025). It was taught by the documented failures of production agents that relied on prompts as their main abstraction.
From compound engineering, FORGE takes the premise that the environment a team builds in is an asset that appreciates (Klaassen, Every, 2025). Effort invested in it compounds across every project that follows. That is why FORGE treats the build environment, the pattern library and the evaluation suites as more strategic than any single deliverable. It is also why the standards, the patterns and the reference builds stay in your repository after the engagement, as plain, versioned files.
FORGE is an assembly of these four, and the assembly is what is distinctive. Measurement comes from the first, accountability from the second, context from the third and compounding from the fourth. FORGE operates them as one path from requirements to running system.
Talk to us about FORGE.
To evaluate the method against a real workload, start with the FORGE Diagnostic. It takes one workload you select and builds a working slice of it to your standards and security controls, inside your own environment. The pipeline is in place from the first commit. In 2 to 4 weeks it is deployed where you can watch it run. You get a readiness assessment of how your current delivery compares, and a proposed next step. You keep the demonstration, its evidence and the assessment, as files in your own repository.